Note
You can download this example as a Jupyter notebook or start it in interactive mode.
Numerical Scaling#
Solvers work best when the numbers in a problem sit in a narrow band around 1. When a model mixes tiny and huge coefficients the matrix is badly scaled, and that hurts the solver: slower factorisations, weaker numerical tolerances, and warnings such as gurobi’s “Matrix range” messages. Scaling is the standard cure. It rewrites the problem in better-behaved units without changing what the problem means.
linopy lets you set a scaling factor on every variable, constraint and on the objective. The factors only change the numbers handed to the solver. Solutions, dual values and the objective are transformed back to your original units automatically, so a scaled model and an unscaled one give the same answer.
Where |
|
Acts on |
|---|---|---|
variable (column) |
solver column holds |
one column |
constraint (row) |
left-hand-side coefficients and right-hand side |
one row |
objective |
linear and quadratic objective coefficients |
the cost row |
This notebook builds a deliberately badly-scaled model, then applies each of the three variants and shows the coefficient range shrink while the solution stays put. For the exact export formulas see the Numerical scaling section of the user guide.
[1]:
import matplotlib.pyplot as plt
import numpy as np

import linopy

linopy.options["semantics"] = "v1"
A badly-scaled model#
A tiny energy example, in awkward units on purpose:
p— a generator’s capacity in GW, at most1e-3GW (i.e. 1 MW).e— energy delivered in MWh, on the order of500.a link constraint converting capacity to energy with a
1e6factor.a demand of at least
500MWh.an objective that prices
pat3e-4andeat2.
The link constraint alone puts a 1e6 next to a 1, so the coefficient matrix spans six orders of magnitude. That is exactly the kind of range that upsets a solver.
The build function below takes one scaling factor per variant, each defaulting to 1.0 (no scaling), so we can switch variants on one at a time.
[2]:
def build(scale_p=1.0, scale_link=1.0, scale_obj=1.0):
    m = linopy.Model()
    p = m.add_variables(lower=0, upper=1e-3, name="p", scaling=scale_p)
    e = m.add_variables(lower=0, name="e")
    m.add_constraints(1e6 * p - e == 0, name="link", scaling=scale_link)
    m.add_constraints(e >= 500, name="demand")
    m.add_objective(3e-4 * p + 2 * e, scaling=scale_obj)
    return m


def coeff_range(m):
    """Smallest, largest, and ratio of the non-zero |A| entries."""
    a = np.abs(m.matrices.A.toarray())
    nz = a[a != 0]
    return nz.min(), nz.max(), nz.max() / nz.min()


def solve(m):
    m.solve(solver_name="highs", output_flag=False)
    return dict(
        p=float(m.solution["p"]),
        e=float(m.solution["e"]),
        objective=m.objective.value,
        demand_dual=float(m.dual["demand"]),
    )
[3]:
base = build()
lo, hi, ratio = coeff_range(base)
print(f"coefficient range: {lo:g} .. {hi:g}  (ratio {ratio:g})")
print("solution:", solve(base))
coefficient range: 1 .. 1e+06  (ratio 1e+06)
solution: {'p': 0.0005, 'e': 500.0, 'objective': 1000.00000015, 'demand_dual': 2.0000000003}
The ratio is 1e6. Now we bring each part of the model into a healthier range.
Variant 1 — variable (column) scaling#
scaling=s on a variable tells the solver to work with the column s · x instead of x. Its bounds are multiplied by s and every coefficient that references it is divided by s. Pick s to pull the variable’s typical magnitude towards 1.
p lives around 1e-3, so scale_p = 1e3 makes the solver-side capacity column sit near 1 and divides the 1e6 link coefficient down to 1e3.
[4]:
var_scaled = build(scale_p=1e3)
print("link row coefficients on p and e:", var_scaled.matrices.A.toarray()[0])
lo, hi, ratio = coeff_range(var_scaled)
print(f"coefficient range: {lo:g} .. {hi:g}  (ratio {ratio:g})")
link row coefficients on p and e: [1000.   -1.]
coefficient range: 1 .. 1000  (ratio 1000)
The 1e6 became 1e3 and the range ratio dropped from 1e6 to 1e3.
Variant 2 — constraint (row) scaling#
scaling=s on a constraint multiplies its whole row — both the left-hand-side coefficients and the right-hand side — by s. Use it to lift or lower a row whose numbers are all far from 1.
On top of the variable scaling, scale_link = 1e-3 multiplies the link row (now holding 1e3 and 1) by 1e-3, giving 1 and 1e-3.
[5]:
row_scaled = build(scale_p=1e3, scale_link=1e-3)
print("link row coefficients on p and e:", row_scaled.matrices.A.toarray()[0])
lo, hi, ratio = coeff_range(row_scaled)
print(f"coefficient range: {lo:g} .. {hi:g}  (ratio {ratio:g})")
link row coefficients on p and e: [ 1.    -0.001]
coefficient range: 0.001 .. 1  (ratio 1000)
Variant 3 — objective scaling#
scaling=s on the objective multiplies every objective coefficient by s. It is the row-scaling of the cost row. Our objective mixes 3e-4 and 2; a factor of 1e3 lifts them to 0.3 and 2000, both far easier for the solver than a sub-1e-3 cost.
Putting it together#
We now switch on all three variants and check two things: the coefficient range is far tighter, and the solution, objective and dual are identical to the unscaled model — because scaling never changes the mathematics, only the numbers the solver sees.
[6]:
unscaled = solve(build())
scaled_model = build(scale_p=1e3, scale_link=1e-3, scale_obj=1e3)
lo, hi, ratio = coeff_range(scaled_model)
scaled = solve(scaled_model)

print(f"scaled coefficient range: {lo:g} .. {hi:g}  (ratio {ratio:g})")
print("unscaled solution:", unscaled)
print("scaled solution:  ", scaled)

for key in unscaled:
    np.testing.assert_allclose(unscaled[key], scaled[key], rtol=1e-6)
print("\nsolution, objective and dual round-trip to the original units ✓")
scaled coefficient range: 0.001 .. 1  (ratio 1000)
unscaled solution: {'p': 0.0005, 'e': 500.0, 'objective': 1000.00000015, 'demand_dual': 2.0000000003}
scaled solution:   {'p': 0.0005, 'e': 500.0, 'objective': 1000.00000015, 'demand_dual': 2.0000000003}

solution, objective and dual round-trip to the original units ✓
Visualising the improvement#
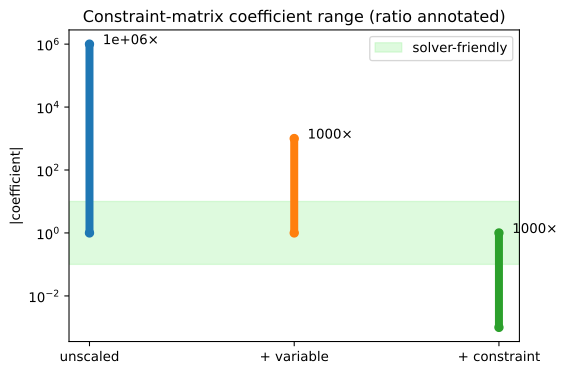
The plot below tracks the non-zero coefficient magnitudes of the constraint matrix as we add each variant. Every bar spans the smallest to the largest |coefficient| on a log scale; the green band marks the solver-friendly region around 1. Each step folds the range back towards it.
[7]:
stages = {
    "unscaled": build(),
    "+ variable": build(scale_p=1e3),
    "+ constraint": build(scale_p=1e3, scale_link=1e-3),
}

fig, ax = plt.subplots(figsize=(6, 4))
ax.axhspan(0.1, 10, color="lightgreen", alpha=0.3, label="solver-friendly")
for x, (name, m) in enumerate(stages.items()):
    lo, hi, _ = coeff_range(m)
    ax.plot([x, x], [lo, hi], "o-", lw=6, solid_capstyle="round")
    ax.annotate(f"{hi / lo:g}×", (x, hi), textcoords="offset points", xytext=(10, 0))
ax.set(
    yscale="log",
    xticks=range(len(stages)),
    xticklabels=list(stages),
    ylabel="|coefficient|",
    title="Constraint-matrix coefficient range (ratio annotated)",
)
ax.legend(loc="upper right")
plt.tight_layout()
Per-coordinate scaling#
A scaling factor does not have to be a scalar. Pass an xarray.DataArray indexed by one of the variable’s or constraint’s dimensions to scale each element differently — handy when the magnitudes vary along a dimension.
[8]:
import pandas as pd
import xarray as xr

i = pd.Index(["cheap", "pricey"], name="i")
m = linopy.Model()
x = m.add_variables(
    lower=0,
    upper=xr.DataArray([1e-3, 1e3], coords=[i]),
    name="x",
    scaling=xr.DataArray([1e3, 1e-3], coords=[i]),
)
m.add_constraints(x.sum() >= 1, name="c")
m.add_objective(x.sum())
print("scaled bounds:", m.matrices.ub)
scaled bounds: [1. 1.]
Notes and caveats#
Scaling never changes the answer. It is a pure change of units. Solutions, duals and the objective are always reported in your original units.
Scaling shifts what solver tolerances mean. A solver applies its feasibility and optimality tolerances to the numbers it sees — the scaled problem — not to your original units. A fixed tolerance therefore maps to a different absolute tolerance per row and column once you scale. That is usually the point (it spreads the tolerances more evenly across the model), but it means a scaled and an unscaled run agree only up to solver tolerance, not bit-for-bit. Rescale if a solver reports numerical trouble, and re-check the tolerances if you rely on tight ones.
Discrete columns stay discrete. For binary and integer variables the scaling factor is stored and round-tripped, but the solver column is left as an ordinary integer column — scaling a discrete variable would break integrality.
Choosing factors. Aim to bring each variable’s magnitude and each row’s coefficients near 1. A good rule of thumb is to divide by the typical absolute value you expect. There is no single correct choice; different solvers and algorithms react differently (barrier methods care least; simplex and crossover benefit most).
This is manual scaling. You provide the factors. An automatic strategy that picks them for you is a natural follow-up built on top of this mechanism.